Normalizing Odds from 10+ Bookmakers: A Data Engineering Deep Dive
How to turn messy, inconsistent bookmaker feeds into one clean, comparable, auditable dataset: canonical models, odds-format conversion, entity resolution, market mapping, de-vigging, validation, and storage in Python and PostgreSQL.
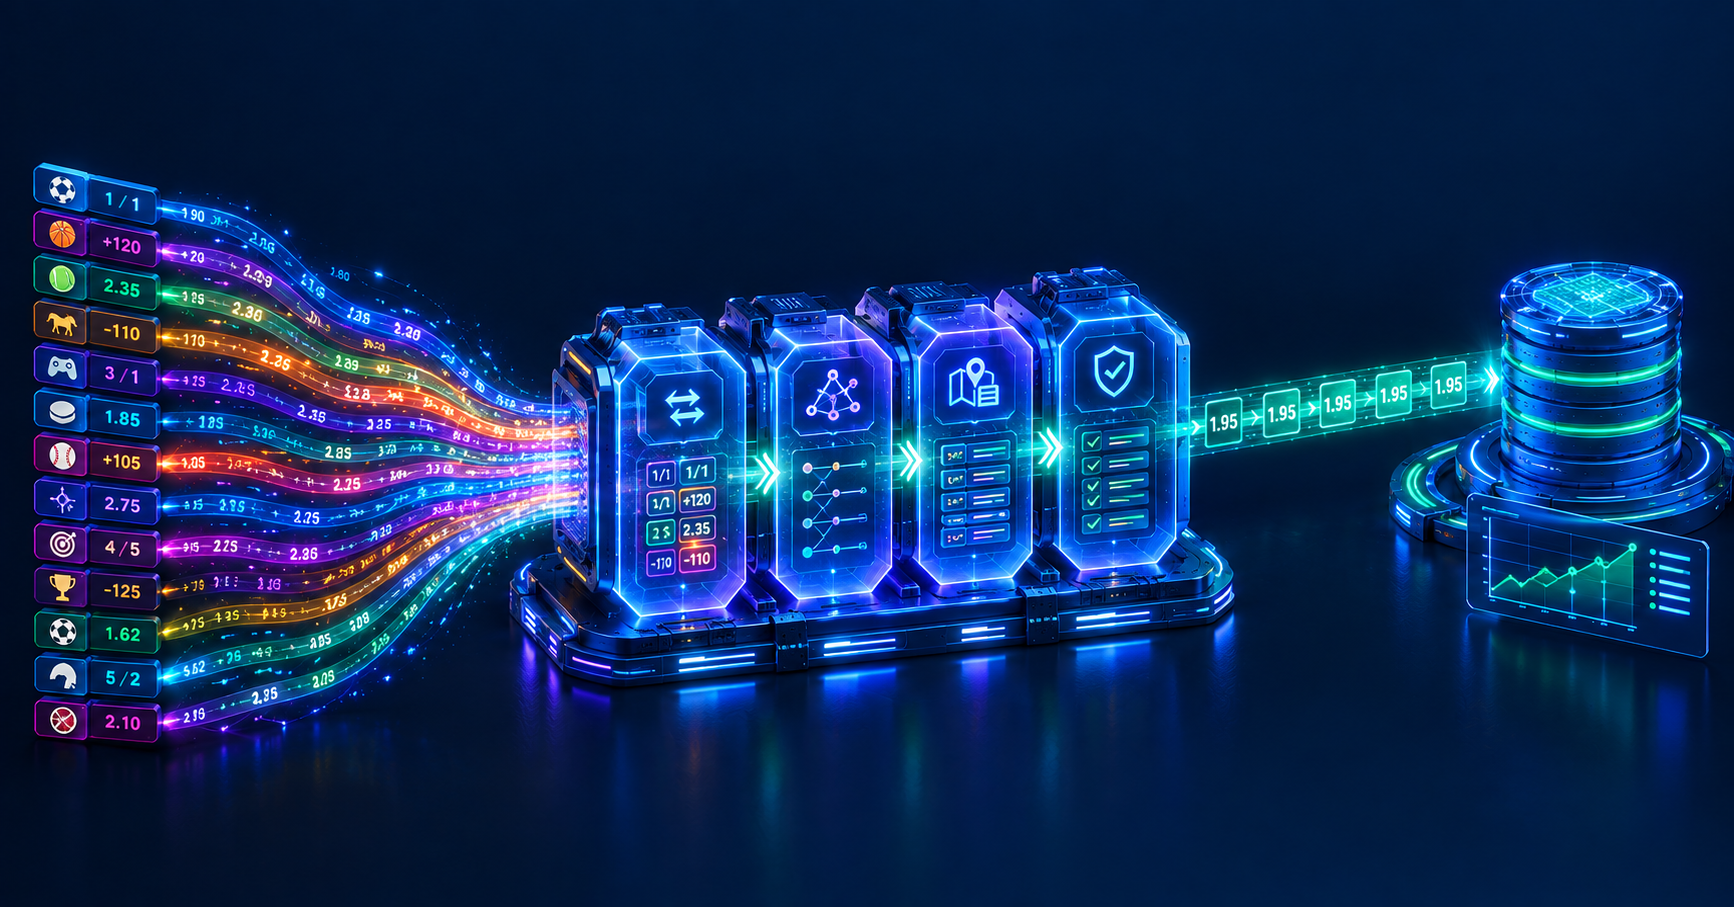
The moment you ingest odds from a second bookmaker, you discover that "odds" is not one data type. One feed sends decimal prices, another sends American moneylines, a third sends fractions as strings. One calls a market match_winner, another calls it 1X2, a third uses a numeric ID that only makes sense with a lookup table you have to request separately. One team is "Manchester United", another is "Man Utd", a third is "Manchester Utd FC". A handicap line arrives as -0.25, meaning your stake is split across two different bets. And every source has its own opinion about what a timestamp means and how to signal that a market is suspended.
Comparing prices across books, computing a consensus, spotting a stale quote, or charting line movement all depend on solving these problems first. Normalization is not glamorous, but it is the foundation that every odds product stands on, and mistakes here silently corrupt everything downstream. This article walks through a production-minded design in Python and PostgreSQL, from the canonical data model to entity resolution to storage.
We will treat the Orbistats sports data API as one of the sources feeding the pipeline. It documents REST and streaming access, publishes a consistent response shape across 13 sports, and offers a free tier you can use to prototype. That shared shape helps enormously, because it means the normalization layer you build for one sport largely carries over to the others. Every payload shape in this article is an illustrative assumption, so inspect real responses in the API sandbox and check the developer documentation before you write your mappers.
A note on scope and responsibility. This is a data engineering article. Nothing here is betting advice, and if you build a product around odds, check the licensing terms of every data source for caching and redistribution, and the legal requirements of the jurisdictions you serve.
Why Odds Normalization Is Harder Than It Looks
It helps to list the problems explicitly, because each one becomes a module in the pipeline.
Price formats differ. Decimal, fractional, American, Hong Kong, Malay, and Indonesian odds all describe the same underlying payout in incompatible ways.
Identity differs. The same real-world match has a different ID at every source, and the participants have different names and spellings.
Taxonomy differs. Markets, selections, and line conventions are named differently everywhere, and some concepts, such as Asian handicaps, do not map one-to-one.
Time differs. Some feeds send the time the bookmaker changed the price, some send the time the provider processed it, and some send neither. Clocks skew, and messages arrive out of order.
State differs. A price can be open, suspended, or removed, and providers signal this differently. Some emit explicit "locked" events, and others simply stop sending a line and expect you to notice.
Quality differs. Every feed occasionally contains stale prices, typos, and impossible values, and a pipeline that trusts them all will eventually publish an arbitrage opportunity that is really a data error.
The Architecture at a Glance
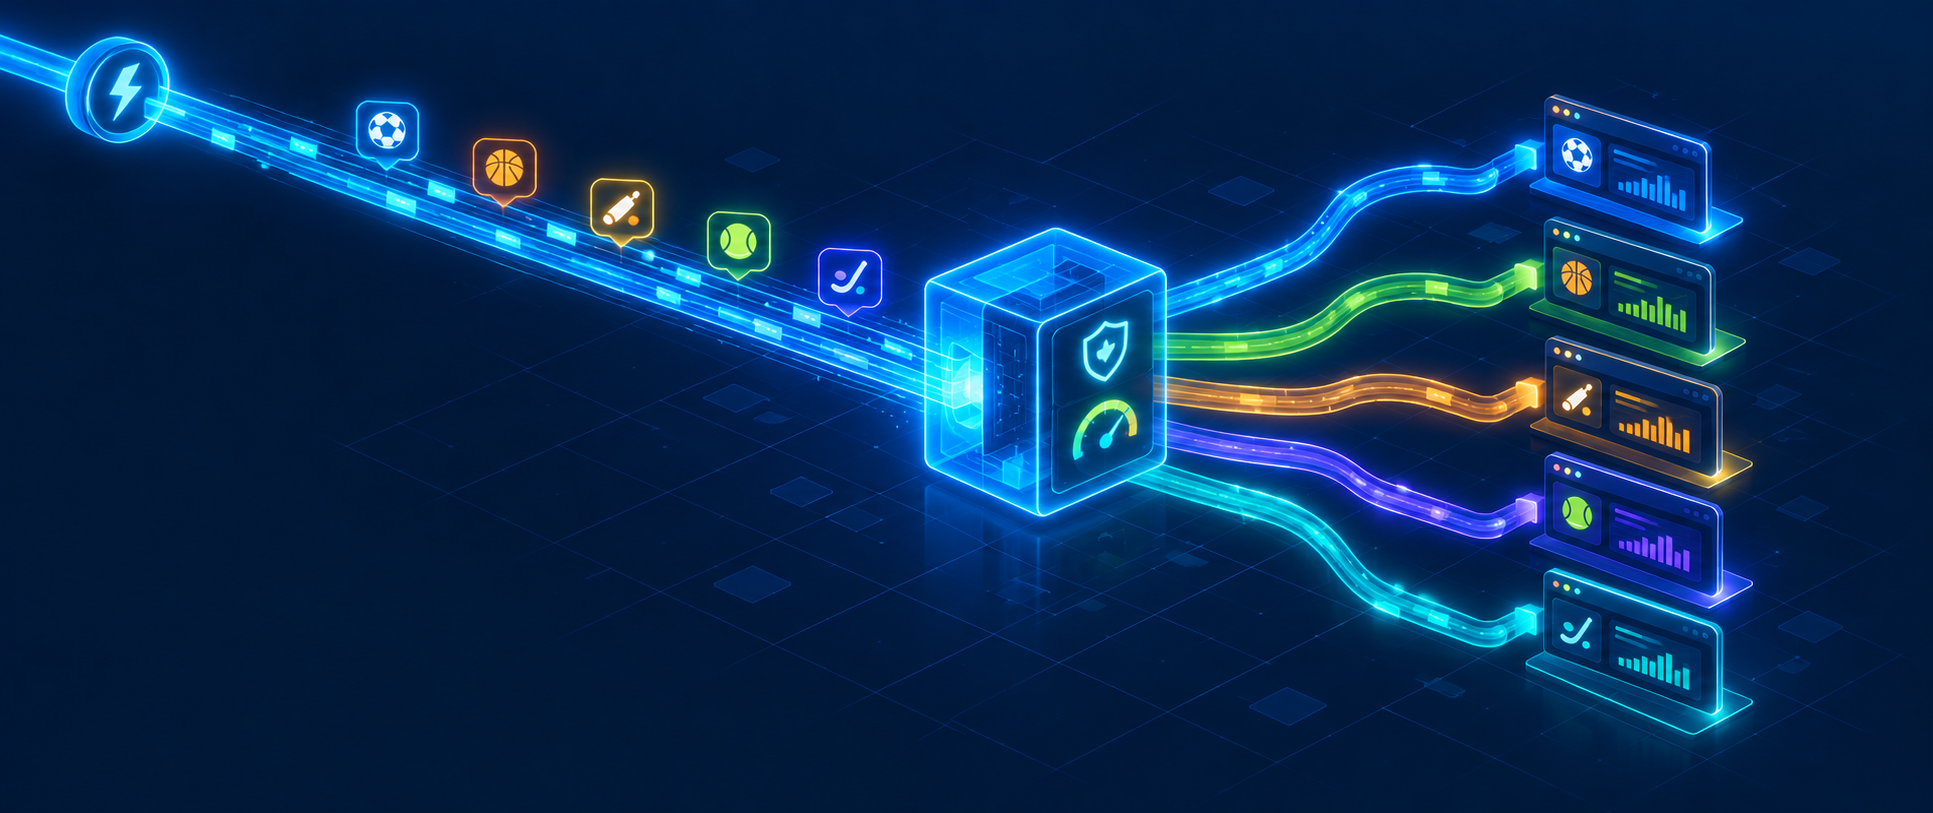
The design principle is to keep raw data immutable and make every transformation reproducible.
Sources (REST / WebSocket / webhooks) |
- Raw store (append-only, untouched payloads) |
- Source adapters (parse per provider) |
- Canonical mapping (format, entity, market, selection, line) |
- Validation and quality flags |
- Current-state store + 6. Change-only history |
- Aggregation (best price, consensus, fair price) | Serving layer (API, cache, streams)
Keeping the raw payload is the most underrated decision. When you discover a mapping bug three weeks later, and you will, you can replay the raw store through the fixed code and repair the history. Without it, the bug is permanent.
Step 1: Design the Canonical Model
Before mapping anything, decide what a normalized quote looks like. Every source will be forced into this shape, so it should be small, strict, and boring.
python
model.py
from dataclasses import dataclass from datetime import datetime from decimal import Decimal from enum import Enum
class Status(str, Enum): OPEN = "open" SUSPENDED = "suspended" REMOVED = "removed"
@dataclass(frozen=True, slots=True) class Quote: event_id: str # canonical event ID, not the source's book: str # canonical bookmaker slug market: str # canonical market key: "1x2", "ou", "ah", "btts" line: Decimal # 0 when the market has no line selection: str # "home", "draw", "away", "over", "under", "yes", "no" price_milli: int # decimal odds x 1000, e.g. 2.50 -> 2500 status: Status source_ts: datetime # when the source says the price was set (UTC) ingest_ts: datetime # when we received it (UTC) raw_ref: str # pointer back to the raw payload
A few decisions in this model are worth explaining. Decimal odds are the canonical format because they are the simplest to compute with: implied probability is just 1 / odds, and payouts multiply directly. Storing the price as an integer number of thousandths avoids floating-point drift, so 2.5 never becomes 2.4999999 after a round trip through arithmetic and JSON. The line uses Decimal for the same reason, since 0.1 + 0.2 != 0.3 is not a property you want in a handicap. Both timestamps are kept, because source_ts tells you how fresh the price is and ingest_ts tells you how slow the pipeline is. And raw_ref gives you an audit trail from any normalized row back to the exact payload that produced it.
Step 2: Convert Every Odds Format to Decimal
Format conversion is the easiest part, but it must be exact and strictly validated. Use Decimal, reject impossible input, and convert everything to the canonical integer only at the very end.
python
odds_formats.py
from decimal import Decimal, ROUND_HALF_UP
def to_milli(decimal_odds: Decimal) -> int: if decimal_odds <= Decimal("1.0"): raise ValueError(f"decimal odds must be > 1.0, got {decimal_odds}") return int((decimal_odds * 1000).quantize(Decimal("1"), rounding=ROUND_HALF_UP))
def american_to_decimal(a: int) -> Decimal: if a == 0: raise ValueError("american odds cannot be 0") if a > 0: return Decimal(1) + Decimal(a) / Decimal(100) return Decimal(1) + Decimal(100) / Decimal(-a)
def fractional_to_decimal(s: str) -> Decimal: num, den = s.strip().split("/") if Decimal(den) == 0: raise ValueError("zero denominator") return Decimal(1) + Decimal(num) / Decimal(den)
def hong_kong_to_decimal(h: Decimal) -> Decimal: if h <= 0: raise ValueError("hong kong odds must be positive") return Decimal(1) + h
def malay_or_indo_to_decimal(x: Decimal) -> Decimal: # Malay and Indonesian odds use the same arithmetic in opposite ranges: # positive = profit per unit staked, negative = stake needed to win one unit. if x == 0: raise ValueError("odds cannot be 0") return Decimal(1) + x if x > 0 else Decimal(1) + Decimal(1) / (-x)
CONVERTERS = { "decimal": lambda v: Decimal(str(v)), "american": lambda v: american_to_decimal(int(v)), "fraction": lambda v: fractional_to_decimal(str(v)), "hk": lambda v: hong_kong_to_decimal(Decimal(str(v))), "malay": lambda v: malay_or_indo_to_decimal(Decimal(str(v))), "indo": lambda v: malay_or_indo_to_decimal(Decimal(str(v))), }
def normalize_price(value, fmt: str) -> int: return to_milli(CONVERTERSfmt)
Notice Decimal(str(v)) rather than Decimal(v). Constructing a Decimal from a float imports the float's binary error, while constructing from its string representation preserves what the source actually sent. It is a tiny habit that prevents a whole class of off-by-one-thousandth bugs. Also note the strict range check in to_milli: a decimal price at or below 1.0 is not a valid quote, so it should raise loudly and go to the quarantine queue rather than sneak through.
python normalize_price(-110, "american") # 1909 (1.909) normalize_price("5/2", "fraction") # 3500 normalize_price("2.50", "decimal") # 2500 Step 3: Resolve Entities, the Real Hard Problem
Odds are only comparable if they are attached to the same event. Matching "the same match" across sources is entity resolution, and it is where most normalization projects spend most of their time.
Build it as layers, from most reliable to least. First, use provider-supplied IDs wherever a stable mapping exists. Second, use an alias table that maps normalized names to canonical participant IDs. Third, for unknown names, fall back to fuzzy matching constrained by sport, competition, and kickoff time. Fourth, send anything below your confidence threshold to a human review queue instead of guessing.
python
entities.py
import re import unicodedata from datetime import timedelta from difflib import SequenceMatcher
NOISE = {"fc", "cf", "afc", "sc", "ac", "as", "cd", "club", "the", "de"}
def norm_name(s: str) -> str: s = unicodedata.normalize("NFKD", s).encode("ascii", "ignore").decode().lower() s = re.sub(r"[^a-z0-9 ]+", " ", s) return " ".join(t for t in s.split() if t not in NOISE)
def similarity(a: str, b: str) -> float: return SequenceMatcher(None, norm_name(a), norm_name(b)).ratio()
def match_event(cand, canon_events, alias_index, tol=timedelta(minutes=30)): """cand: dict with sport, home, away, kickoff (UTC). Returns (event_id, confidence).""" home_id = alias_index.get((cand["sport"], norm_name(cand["home"]))) away_id = alias_index.get((cand["sport"], norm_name(cand["away"])))
best_id, best_score = None, 0.0
for ev in canon_events:
    if ev["sport"] != cand["sport"]:
        continue
    if abs(ev["kickoff"] - cand["kickoff"]) > tol:
        continue

    if home_id and away_id:
        if (ev["home_id"], ev["away_id"]) == (home_id, away_id):
            return ev["event_id"], 1.0          # exact via alias table
        continue

    score = min(similarity(cand["home"], ev["home_name"]),
                similarity(cand["away"], ev["away_name"]))
    if score > best_score:
        best_id, best_score = ev["event_id"], score

return (best_id, best_score) if best_score >= 0.88 else (None, best_score)
Some design notes. The min of the home and away scores is deliberate: a strong match on one team and a weak match on the other should not pass. The kickoff window is a hard filter because two teams can meet twice in a short span in cup competitions, and time is your best disambiguator. Anything that returns None should be written to a review table with the candidate and the top guesses, and every human decision should be saved to the alias table, so the system gets more accurate the longer it runs. Never auto-create a canonical event from a low-confidence match, because duplicate events split your data and wrong merges poison it, and wrong merges are far harder to detect.
Keep the threshold conservative. A missed match costs you some coverage for a few minutes. A wrong match publishes a price for the wrong game.
Step 4: Map Markets, Selections, and Lines
Next, translate every source's market vocabulary into your canonical taxonomy. Keep this as data, not code, so that adding a bookmaker means adding a mapping, not writing a new function.
python
markets.py
from decimal import Decimal
(source, source_market_key) -> canonical market + selection mapping
MARKET_MAP = { ("orbistats", "match_winner"): { "market": "1x2", "selections": {"1": "home", "x": "draw", "2": "away", "home": "home", "draw": "draw", "away": "away"}, }, ("orbistats", "over_under"): { "market": "ou", "selections": {"over": "over", "under": "under"}, }, ("bookB", "MONEYLINE"): { "market": "1x2", "selections": {"H": "home", "D": "draw", "A": "away"}, }, }
def map_market(source: str, market_key: str, selection_key: str):
spec = MARKET_MAP.get((source, market_key))
if not spec:
return None # unknown market: quarantine, do not guess
sel = spec["selections"].get(str(selection_key).strip().lower())
or spec["selections"].get(str(selection_key).strip())
return (spec["market"], sel) if sel else None
def normalize_line(raw) -> Decimal: if raw in (None, ""): return Decimal("0") return Decimal(str(raw)).quantize(Decimal("0.25"))
Unknown markets and selections should return None and be quarantined, never defaulted. A silent fallback such as "treat unknown as 1x2" is how a corner-count market ends up compared against a match result. Track the quarantine volume as a metric, because a sudden spike usually means a source changed its vocabulary.
Handling Asian Handicap Quarter Lines
Quarter lines are a classic trap. A -0.25 handicap is not a single bet: half your stake is placed at 0 and half at -0.5, and the outcome can be a half win or half loss. Comparing it directly against a -0.5 line from another bookmaker is comparing different products. The normalizer should keep the line exactly as offered and provide a helper that exposes the two component lines, so downstream code can reason about them.
python def split_quarter_line(line: Decimal) -> list[Decimal]: if (line * 4) % 2 == 0: # whole or half line return [line] return [line - Decimal("0.25"), line + Decimal("0.25")]
split_quarter_line(Decimal("-0.25")) # [Decimal('-0.50'), Decimal('0.00')] split_quarter_line(Decimal("2.25")) # [Decimal('2.00'), Decimal('2.50')] split_quarter_line(Decimal("2.5")) # [Decimal('2.5')]
Only compare prices across books when the market, the line, and the selection all match exactly. That is what the composite key in the next section enforces.
Step 5: Turn a Raw Payload into Quotes
Now the source adapter ties the previous steps together. Each provider gets a small function that yields canonical quotes from its raw record. The example below shows an assumed shape for an Orbistats-style record, and you should replace the field names with what the sandbox actually returns.
python
adapters.py
from datetime import datetime, timezone from decimal import Decimal from model import Quote, Status from odds_formats import normalize_price from markets import map_market, normalize_line
def parse_ts(s) -> datetime: return datetime.fromisoformat(str(s).replace("Z", "+00:00")).astimezone(timezone.utc)
def adapt_orbistats(raw: dict, resolve_event, raw_ref: str, now: datetime): """Assumed shape: {fixture: {...}, book, market, line, odds: [{selection, price}], updated_at, suspended}""" event_id, confidence = resolve_event(raw["fixture"]) if not event_id: return [], ("unmatched_event", raw_ref)
quotes, rejects = [], []
for o in raw["odds"]:
    mapped = map_market("orbistats", raw["market"], o["selection"])
    if not mapped:
        rejects.append(("unmapped_market", raw_ref))
        continue
    market, selection = mapped
    try:
        price_milli = normalize_price(o["price"], raw.get("format", "decimal"))
    except (ValueError, KeyError, ArithmeticError) as e:
        rejects.append((f"bad_price:{e}", raw_ref))
        continue

    quotes.append(Quote(
        event_id=event_id,
        book=str(raw["book"]).lower(),
        market=market,
        line=normalize_line(raw.get("line")),
        selection=selection,
        price_milli=price_milli,
        status=Status.SUSPENDED if raw.get("suspended") else Status.OPEN,
        source_ts=parse_ts(raw["updated_at"]),
        ingest_ts=now,
        raw_ref=raw_ref,
    ))
return quotes, rejects
The adapter never raises for bad data from the source. It returns rejects with reasons, because in a streaming pipeline one malformed message must not stop the world. Every reject is counted by reason, which turns "the pipeline seems off" into a graph you can alert on.
Step 6: Validate Before You Trust
Normalized does not mean correct. A price can be perfectly well-formed and still wrong. Add a validation stage that attaches quality flags rather than silently dropping data, so consumers can decide how strict to be.
Two checks do most of the work. The first is the overround check: for a complete market, the sum of implied probabilities minus one is the bookmaker's margin, which should fall in a sane range. A margin near zero or negative means either an exchange, a stale price, or an error, and a margin above roughly 25 percent usually means a missing selection or a bad number. The second is peer comparison: a price far from what other books are offering for the same selection deserves suspicion.
python
validate.py
from statistics import median
def overround(prices_milli: list[int]) -> float: return sum(1000 / p for p in prices_milli) - 1.0
def market_flags(prices_milli: list[int], expected_selections: int) -> list[str]: flags = [] if len(prices_milli) != expected_selections: flags.append("incomplete_market") return flags o = overround(prices_milli) if o < -0.005: flags.append("negative_margin") elif o > 0.25: flags.append("excessive_margin") return flags
def is_outlier(price_milli: int, peers_milli: list[int], k: float = 6.0) -> bool: if len(peers_milli) < 4: return False # too few peers to judge m = median(peers_milli) mad = median(abs(p - m) for p in peers_milli) scale = max(1.4826 * mad, 0.01 * m) # floor prevents false positives return abs(price_milli - m) / scale > k
Median absolute deviation is used instead of standard deviation because a single bad quote inflates the standard deviation and hides itself, whereas the median barely moves. The scale floor matters: when all peers agree almost exactly, the MAD approaches zero and every tiny difference would look infinitely suspicious.
Treat these as flags, not deletions. A genuine sharp move by one bookmaker looks exactly like an outlier for a short time, and a good pipeline preserves it while marking it so downstream consumers can choose.
Also add a freshness check. A quote whose source_ts is older than your staleness limit for that market type should be flagged, and prices from suspended or removed states should never participate in best-price or consensus calculations.
Step 7: Store Current State and History Separately
Two access patterns pull in opposite directions, so use two tables. Serving the current price for an event needs a small, fast, upsert-friendly table. Analyzing line movement needs an append-only history that grows continuously and must be cheap to write.
sql -- current state: one row per (event, book, market, line, selection) CREATE TABLE odds_current ( event_id text NOT NULL, book text NOT NULL, market text NOT NULL, line numeric(6,2) NOT NULL DEFAULT 0, -- 0 when the market has no line selection text NOT NULL, price_milli integer NOT NULL CHECK (price_milli > 1000), status text NOT NULL, source_ts timestamptz NOT NULL, ingest_ts timestamptz NOT NULL, flags text[] NOT NULL DEFAULT '{}', PRIMARY KEY (event_id, book, market, line, selection) );
CREATE INDEX odds_current_event ON odds_current (event_id, market);
-- history: append-only, partitioned by day, written only on change CREATE TABLE odds_history ( event_id text NOT NULL, book text NOT NULL, market text NOT NULL, line numeric(6,2) NOT NULL, selection text NOT NULL, price_milli integer NOT NULL, status text NOT NULL, source_ts timestamptz NOT NULL, ingest_ts timestamptz NOT NULL ) PARTITION BY RANGE (ingest_ts);
The upsert has one important guard: ignore anything older than what you already hold. Feeds deliver out of order, especially around reconnects, and letting an old message overwrite a newer price is a subtle way to show users stale odds.
sql INSERT INTO odds_current (event_id, book, market, line, selection, price_milli, status, source_ts, ingest_ts, flags) VALUES ($1,$2,$3,$4,$5,$6,$7,$8,$9,$10) ON CONFLICT (event_id, book, market, line, selection) DO UPDATE SET price_milli = EXCLUDED.price_milli, status = EXCLUDED.status, source_ts = EXCLUDED.source_ts, ingest_ts = EXCLUDED.ingest_ts, flags = EXCLUDED.flags WHERE odds_current.source_ts < EXCLUDED.source_ts; Write History Only When Something Changed
Live feeds repeat prices constantly. If a bookmaker re-sends an unchanged price every second, storing every message multiplies your storage by orders of magnitude while adding no information. Compare each new quote against the last known state for its key and append to history only on a real change of price or status.
python
changes.py
class ChangeDetector: def init(self): self.last = {} # key -> (price_milli, status, source_ts)
def key(self, q):
    return (q.event_id, q.book, q.market, q.line, q.selection)

def accept(self, q) -> str:
    k = self.key(q)
    prev = self.last.get(k)
    if prev and q.source_ts <= prev[2]:
        return "stale"                       # out of order or duplicate
    self.last[k] = (q.price_milli, q.status, q.source_ts)
    if prev and (prev[0], prev[1]) == (q.price_milli, q.status):
        return "unchanged"                   # refresh current, skip history
    return "changed"
The in-memory map is a cache, not the source of truth. On startup, warm it from odds_current, and in a multi-worker setup partition your workers by event ID, so every quote for an event lands on the same worker and the detector stays consistent. Once a table grows into the hundreds of millions of rows, consider a time-series extension or columnar storage for the history, and downsample old data, for example keeping every change for a week and one-minute snapshots afterward.
Step 8: Aggregate, Best Price, Consensus, and Fair Price
With clean, comparable quotes you can finally do the useful things. Best price per selection is a simple maximum, but keep track of which bookmaker offers it. Consensus and fair price need one more idea: removing the bookmaker margin, often called de-vigging.
The simplest approach is proportional normalization, which scales implied probabilities so they sum to one. It is easy to explain and reasonable for balanced markets. Its weakness is that it removes the margin equally from all outcomes, while real bookmakers tend to load more margin onto longshots. The power method models that by finding an exponent that makes the probabilities sum to one, which shrinks longshot probabilities more than favorites.
python
fair.py
def fair_proportional(prices_milli: list[int]) -> list[float]: inv = [1000 / p for p in prices_milli] s = sum(inv) return [x / s for x in inv]
def fair_power(prices_milli: list[int]) -> list[float]: inv = [1000 / p for p in prices_milli] if sum(inv) <= 1.0: return fair_proportional(prices_milli) lo, hi = 1.0, 1000.0 # find k >= 1 with sum(inv**k) == 1 for _ in range(100): mid = (lo + hi) / 2 if sum(x ** mid for x in inv) > 1.0: lo = mid else: hi = mid k = (lo + hi) / 2 return [x ** k for x in inv]
def best_prices(quotes_by_book: dict[str, dict[str, int]]) -> dict[str, tuple[str, int]]: """quotes_by_book: {book: {selection: price_milli}} -> {selection: (book, price)}""" best = {} for book, sels in quotes_by_book.items(): for sel, price in sels.items(): if sel not in best or price > best[sel][1]: best[sel] = (book, price) return best
def consensus_fair(quotes_by_book, selections): per_book = [] for sels in quotes_by_book.values(): if all(s in sels for s in selections): # only complete markets per_book.append(fair_power([sels[s] for s in selections])) if not per_book: return None med = [sorted(col)[len(col) // 2] for col in zip(*per_book)] total = sum(med) return {s: p / total for s, p in zip(selections, med)}
Two rules keep this honest. Only include complete markets from each bookmaker when computing fair prices, since removing margin from a partial market gives nonsense. And exclude flagged, stale, suspended, and outlier quotes from the consensus, or a single broken feed will drag everyone's fair price with it. Whatever method you choose, label it in your product. "Fair price" is a model output, not a fact, and different methods disagree most on lopsided markets.
Step 9: Make It Idempotent and Replayable
A pipeline that cannot be safely re-run is a pipeline that cannot be fixed. Design every stage so that processing the same input twice produces the same result.
Store raw payloads in an append-only location, partitioned by source and date, with a stable reference you can put in raw_ref. Newline-delimited JSON compressed with gzip is enough to start, and columnar files are better at scale. Make the upsert conditional on source_ts, as shown above, so replays cannot overwrite newer data with older data. Derive history rows deterministically from the change detector so a replay does not duplicate them, for example by adding a unique constraint on the history key plus source_ts. Then a replay harness becomes trivial: read the raw store for a time range, run it through the current adapters, and compare the output against what is stored.
python
replay.py (sketch)
def replay(raw_records, adapters, resolver, sink): for ref, source, payload in raw_records: quotes, rejects = adapters[source](payload, resolver, ref, now_utc()) sink.write(quotes, rejects)
This is what turns a mapping bug from a data-quality disaster into an afternoon of work: fix the mapper, replay the affected window, and the history heals.
Step 10: Test the Pipeline Like a Data Product
Normalization code is mostly pure functions, which makes it very testable, and the tests are worth far more than they cost. Use three layers.
Golden files: keep a few real raw payloads from each source, along with the exact normalized output you expect. Any change to a mapper that alters the output shows up as a diff you must consciously approve.
Property-based tests: state invariants that must hold for all inputs and let the framework hunt for counterexamples.
python
test_fair.py
from hypothesis import given, strategies as st from fair import fair_power, fair_proportional
prices = st.lists(st.integers(min_value=1010, max_value=50_000), min_size=2, max_size=4)
@given(prices) def test_fair_probabilities_sum_to_one(p): assert abs(sum(fair_power(p)) - 1.0) < 1e-6 assert abs(sum(fair_proportional(p)) - 1.0) < 1e-9
@given(prices) def test_higher_price_means_lower_fair_probability(p): fair = fair_proportional(p) for i in range(len(p)): for j in range(len(p)): if p[i] > p[j]: assert fair[i] <= fair[j]
Replay tests: run a recorded hour of real traffic through the pipeline in CI and assert on aggregate outcomes such as the reject rate, the unmatched-event rate, and the number of changed quotes. A sudden jump in any of them is an early warning that a source changed its format.
Step 11: Operate It, Metrics and Pitfalls
A normalization pipeline fails quietly, so instrument it. Track the unmatched-event rate and unmapped-market rate per source, since they are the leading indicators of a vocabulary change. Track the reject rate by reason, quote freshness (ingest_ts - source_ts) per source, the fraction of quotes flagged as outliers, and the ratio of unchanged to changed quotes, which tells you how much your change detection is saving. Alert on trends, not single events.
The most common pitfalls are worth stating plainly. Guessing when a mapping is unknown corrupts data quietly, so quarantine instead. Comparing prices across different lines is the classic handicap and totals mistake. Trusting provider timestamps blindly breaks ordering when clocks skew, so compare against your own ingest time as well. Averaging raw implied probabilities across books without removing margin biases every result upward. Storing floats for prices produces phantom changes and failed equality checks. Forgetting to handle removed lines leaves ghost prices in your current-state table long after the bookmaker pulled them, so expire quotes that have not been refreshed within a sensible window. And treating a free tier as a production data source will bite you on match day, so check plan limits and licensing on the pricing page before you build a public product on any feed.
Using Orbistats as a Source
As a data source, Orbistats fits this pipeline in a few useful ways. The consistent response structure across 13 sports means your adapter and mapping tables are mostly reusable, so adding a sport is largely a matter of adding market keys rather than writing new parsing logic. The REST endpoints are convenient for backfilling and reference data, while the streaming and webhook options documented in the developer documentation suit live updates, and the same ingestion, retry, and reconnection patterns apply that are covered in the vanilla JavaScript WebSocket scoreboard and the 50-line live scoreboard tutorial. For event-driven side effects, the idempotency lessons in the Go webhook receiver guide apply directly to the "replayable and idempotent" requirement above.
Before wiring anything into production, confirm the current sports list, endpoint names, update frequencies, and plan limits, and check the terms for how long you may cache data and whether you may redisplay it next to other providers' prices.
The Design Checklist
Keep raw payloads immutable and replayable. Define a small strict canonical model with integer prices and exact decimals for lines. Convert every odds format through validated Decimal arithmetic. Resolve events with layered matching, a conservative threshold, and a human review queue that feeds an alias table. Map markets from data, quarantine anything unknown, and never compare across different lines. Attach quality flags instead of silently dropping suspicious quotes. Separate current state from change-only history, and guard upserts against out-of-order data. De-vig before you compare, exclude bad quotes from consensus, and label your fair-price method. Make every stage idempotent so replays heal history. Test with golden files, properties, and recorded traffic. And instrument the vocabulary drift that will eventually happen.
Where to Go Next
The fastest way to see real payloads is to open the Orbistats API sandbox, then create a free key from the Orbistats site and read the developer documentation. If your ingestion service is not written in Python, the client patterns are also covered in the Go client tutorial, the .NET Core example, and the Python and FastAPI guide. Compare plan limits on the pricing page, and find more guides on the Orbistats DEV profile.
Odds normalization is one of those problems where the boring work is the valuable work. Get the model, the identities, and the audit trail right, and every product you build on top becomes easier. Get them wrong, and you will be debugging phantom arbitrage at midnight. If you build this, tell me in the comments which bookmaker's data was the messiest.